23-sample evaluation
ClaimVakeel
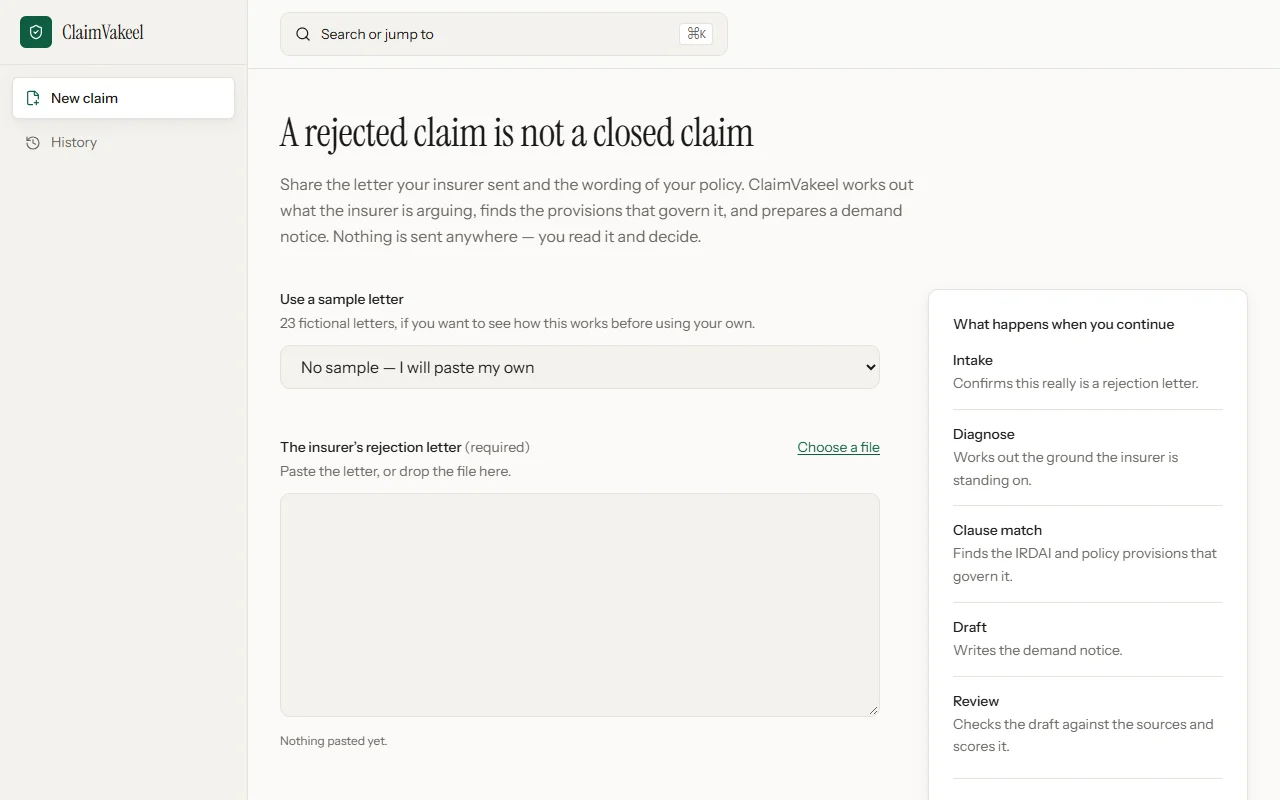
From insurance rejection letter to a reviewed appeal draft
- Year
- 2026
- Role
- Agent pipeline, evaluation & review interface
- Context
- RocketRide Buildathon
- Stack
- Next.js, TypeScript, Ollama, Zod, SQLite, Drizzle
Overview
Five agent stages read a rejection letter, diagnose the denial, match policy clauses and draft an appeal for human review. Citation checks and confidence gates route uncertain cases to a person.
How it works
- Five stages separate intake, diagnosis, clause matching, drafting and adversarial review, with Zod-validated outputs.
- Citations are checked against the supplied policy and a fixed clause corpus; unsupported statements and low confidence route the claim to human review.
- Local Ollama execution with an optional Anthropic provider, plus per-stage traces, retries and JSON repair.
- A 23-sample batch evaluation records latency, token use, cost and expected outcomes, and fails if a broken document produces a draft.
- Human approval lives in the app so a reviewer can return later without keeping an agent run open.
Prototype evaluated on fictional letters. The clause corpus is condensed and requires verification before real use. The local engine is the evaluated path; RocketRide execution is not yet verified end to end.
Next project
Curio